> For the complete documentation index, see [llms.txt](https://studio.docs.ai.vonage.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://studio.docs.ai.vonage.com/voice/nodes/basic/q-and-a-node.md).
# Q\&A Node
## Overview
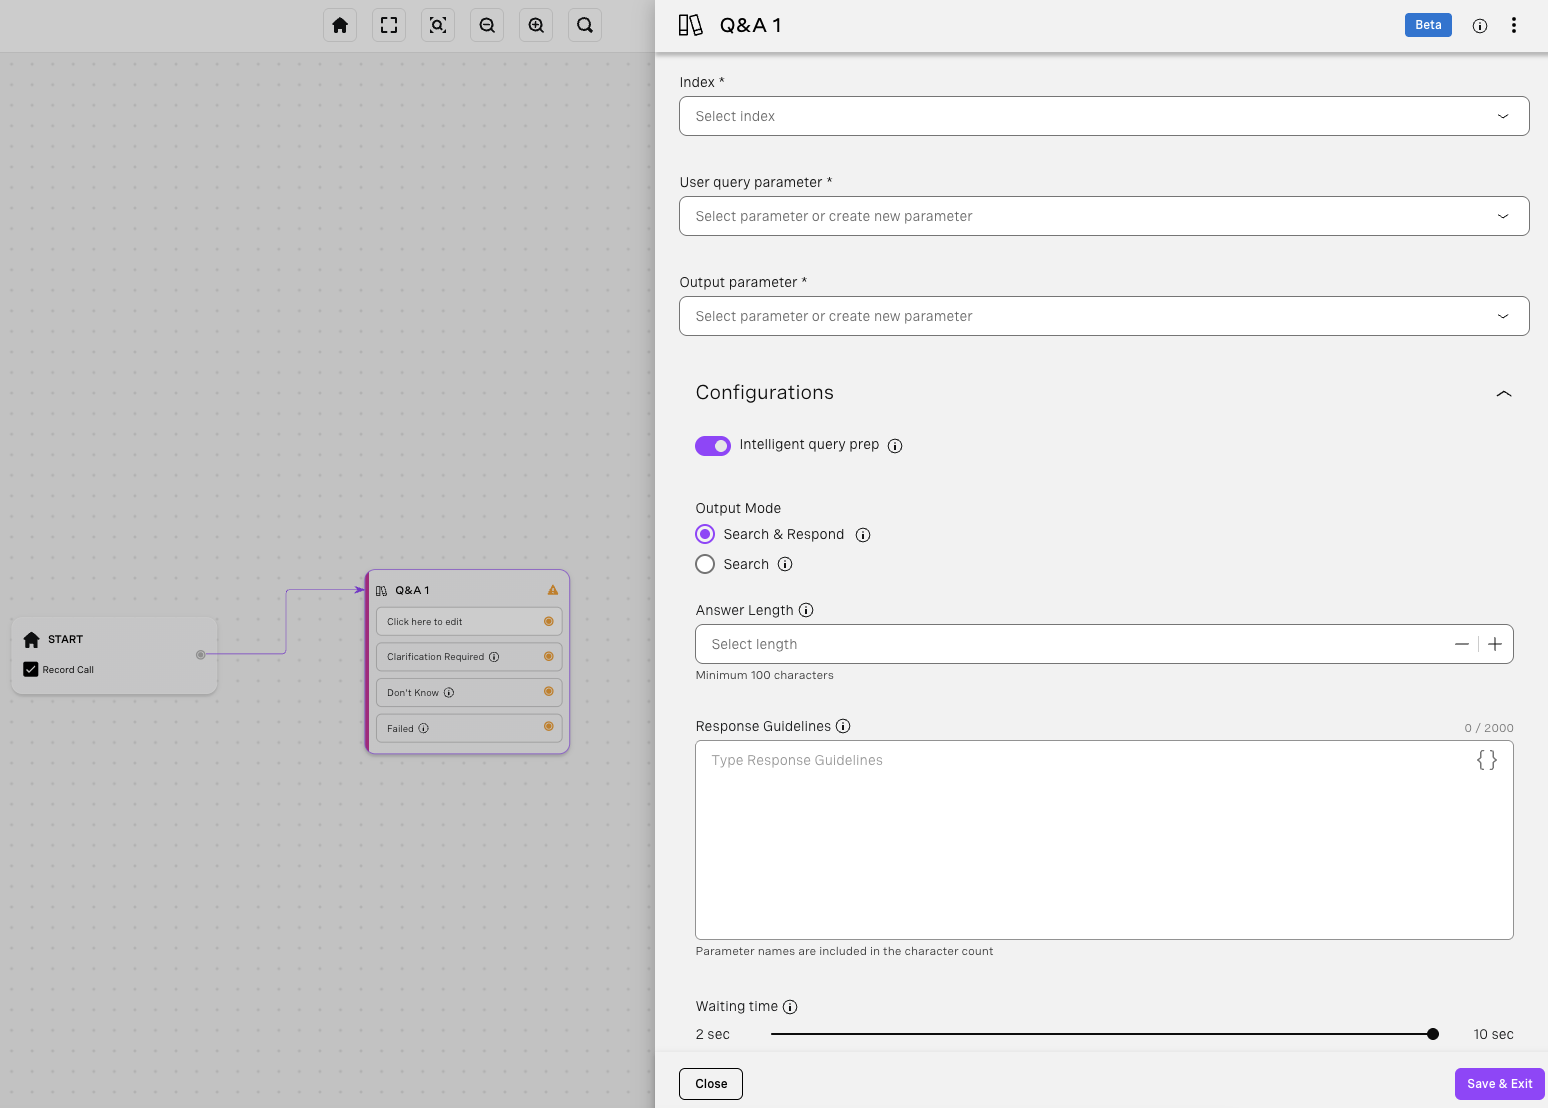
The **Q\&A node** allows your Virtual Assistant (VA) to access the Indexes you have created in the [Knowledge AI](https://studio.docs.ai.vonage.com/ai-studio/knowledge-ai) tab and generate accurate, context-aware answers based on your content. Instead of relying on predefined intents and entities, it uses your uploaded materials, known as **Sources**, to dynamically respond to user inquiries. Responses are generated using the Knowledge AI RAG (Retrieval-Augmented Generation) pipeline, which combines Vonage's proprietary Semantic Search with Google Gemini's large language models (LLMs).
***
## Prerequisties
| Prerequisite | Details |
| --------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Knowledge AI tab configured | The Knowledge AI tab must be set up with at least one Index before you configure the Q\&A node. For setup instructions, see [Knowledge AI](https://studio.docs.ai.vonage.com/ai-studio/knowledge-ai). |
***
## Limitations
| Limitation | Details |
| ------------------------------- | -------------------------------------------------------------------------------------------------------------------------- |
| Single Index per node | Each Q\&A node is restricted to one Index. |
| Single VA per Index | Indexes are scoped to one VA per API key. |
| Single-turn processing | The Q\&A node processes one input and returns one output. It does not support back-and-forth conversation. |
| Non-deterministic answer length | Exact control over response length is not guaranteed due to the non-deterministic nature of the LLMs used by Knowledge AI. |
***
## Setting up the Q\&A Node
To configure the Q\&A node:
{% stepper %}
{% step %}
### Select an Index
Choose one Index to serve as the knowledge base for that node. Only Indexes created under the API key for the selected VA that are not already in use by another VA appear in the dropdown. Each Q\&A node supports one Index. To access different Sources across different parts of your flow, use multiple Q\&A nodes and assign a different Index to each.
For more information, see the [Group Your Sources to Create Indexes](https://studio.docs.ai.vonage.com/ai-studio/knowledge-ai#group-your-sources-to-create-indexes) section on the Knowledge AI page.
{% hint style="success" %}
**Managing Indexes across multiple Q\&A nodes and VAs**
* To handle different knowledge domains within the same VA, use multiple Q\&A nodes and assign a different Index to each.
* Indexes are restricted to one VA per API key. If you cannot find an Index in the dropdown, check whether it is already in use by another VA.
* To use the same content across multiple VAs under the same API key, duplicate the Index and assign it to the other VA. For instructions, see the [Duplicating an Index](https://studio.docs.ai.vonage.com/ai-studio/knowledge-ai#duplicating-an-index) section on the Knowledge AI page.
{% endhint %}
{% endstep %}
{% step %}
### Assign the user query parameter
Select the parameter from the **User Query** dropdown that captures the user input. Knowledge AI processes this value to generate a response.
{% endstep %}
{% step %}
### Capture the output
Under the **Output Parameter** dropdown, select the parameter to store the generated answer. Pass this parameter into a Speak/Send Message or Collect Input node to deliver the response to the end user.
{% hint style="warning" %}
**Expected processing delay**
There may be a 2- to 5-second delay while the system processes the query and generates the response.
{% endhint %}
{% endstep %}
{% endstepper %}
***
## Exit paths
The Q\&A node has four exit paths that determine how your VA flow continues after the node processes a user query.
| Exit path | Trigger condition |
| ---------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Knowledge AI response | Knowledge AI successfully retrieves and returns a relevant answer from the knowledge base. |
| Don't Know | Knowledge AI cannot find a suitable answer in the knowledge base. |
| Failed | A runtime error occurs, or the waiting time is exceeded. |
| Clarification Required | Knowledge AI identifies that the user query requires additional context or clarification before a response can be generated. This path is triggered when the input is too ambiguous, incomplete, or brief to retrieve a relevant answer accurately. |
### Handling the Clarification Required path
When Knowledge AI detects that a query is too ambiguous to process, it triggers the **Clarification Required** exit path. Use this path to route the user to a follow-up prompt that requests more context. Once the user provides a more complete query, route the flow back to the Q\&A node to process the refined input.
The following table shows examples of unclear or incomplete inputs and suggested VA follow-up questions:
| User input | Intended meaning | Suggested VA follow-up question |
| ----------------------- | ---------------------------------------------- | -------------------------------------------------------------------------- |
| "benefits" | "What is the company benefits policy?" | "What is your question about benefits?" |
| "work from home policy" | "What is the company's work-from-home policy?" | "Are you asking about eligibility, the application process, or equipment?" |
| "data privacy EU law" | "What does EU law say about data privacy?" | "Are you asking about GDPR requirements or data processing obligations?" |
{% hint style="info" %}
**Clarification Required and Intelligent query prep**
The **Intelligent query prep** switch affects how Knowledge AI interprets queries in the context of conversation history. The **Clarification Required** exit path is triggered independently by the RAG pipeline when it determines that the query itself is too ambiguous to retrieve a relevant answer, regardless of the switch state.
{% endhint %}
## Configurations
### Intelligent query prep (Optional)
The **Intelligent query prep** switch allows Knowledge AI to understand and respond to follow-up queries based on the ongoing conversation, without requiring the user to restate previous context. This setting is available in both the Q\&A node and the [Index Tester](https://studio.docs.ai.vonage.com/ai-studio/knowledge-ai#test-your-indexes). To access it in the Index Tester, select the gear icon at the top-right corner of the interface.
| Behavior | Intelligent prep query is ON | Intelligent prep query is OFF |
| ------------------------------------- | ----------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------ |
| Context handling | Enables contextual understanding for follow-up questions. Uses session conversation history to interpret meaning. | Each query is processed independently. |
| Latency | Adds 300 to 1000 ms as Knowledge AI retrieves and processes context. | No additional latency. |
| Responses when context is unavailable | N/A | May produce "I don't know" responses if context is required. |
Examples
The following tables show examples of how the toggle affects VA responses:
**Example 1: Cancellation charges**
| Speaking party | Intelligent query prep ON | Intelligent query prep OFF |
| -------------- | --------------------------------------- | --------------------------------------- |
| End User | What is the price of an economy ticket? | What is the price of an economy ticket? |
| VA | It is $1000. | It is $1000. |
| End User | What are its cancellation charges? | What are its cancellation charges? |
| VA | Cancellation charges are $250. | Sorry, I don't know. |
With Intelligent query prep ON, Knowledge AI uses the conversation history to link "its" to "economy ticket." With Intelligent query prep OFF, the VA treats each query as a new question and cannot infer context.
**Example 2: Animals on a plane**
| Speaking party | Intelligent query prep ON | Intelligent query prep OFF |
| -------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------- |
| End User | What animals are allowed on a plane? | What animals are allowed on a plane? |
| VA | Passengers can bring up to two animals (dogs or cats) in approved containers, either in the cabin or cargo hold. | Passengers can bring up to two animals in approved containers. |
| End User | Give me more details! | Give me more details! |
| VA | Containers must not exceed 118 cm (55 × 40 × 23 cm) or 47 in (22 × 16 × 9 in), with a total weight of 8 kg. They must be leak-proof and lined with absorbent material. | Sorry, I don't know. |
With Intelligent query prep ON, Knowledge AI uses the conversation history to understand that "more details" refers to the previous answer about animals. With Intelligent query prep OFF, the VA cannot infer context and cannot provide additional information.
{% hint style="success" %}
**Recommended setting**
Keep this switch ON for smoother, more human-like interactions.
Turn it OFF if each query is unrelated or if lower latency is required.
Always test your VA flows to understand how context affects accuracy and response time.
{% endhint %}
### Answer length (Optional)
Use **Answer length** to control how detailed Knowledge AI's responses should be.
Choose whether the response should be:
* Shorter: suitable for simple answers.
* Longer: suitable for complex, context-heavy queries.
The minimum is 100 characters or 20 words, with no upper limit. This field is disabled when **Output mode** is set to [Search](https://studio.docs.ai.vonage.com/voice/nodes/basic/q-and-a-node#search).
| Setting | Behaviour |
| ----------- | --------------------------------------------------------------------------------------------------------------------------------- |
| Not defined | Knowledge AI automatically determines the best answer length based on the query and the knowledge base. |
| Defined | Knowledge AI treats the value as a soft constraint. The response will generally fall within a small range of the specified value. |
{% hint style="warning" %}
**Latency and accuracy trade-off**
Longer answers increase accuracy but also increase latency. Exact control over response length is not guaranteed due to the non-deterministic nature of the LLMs used by Knowledge AI. Treat the Answer length value as a soft constraint and test your flows to find the setting that works best for your use case.
{% endhint %}
#### Response guidelines (Optional)
{% hint style="warning" %}
**Response guidelines availability**
The **Response guidelines** field is disabled in both the Q\&A node and the Index Tester when **Output mode** is set to [Search](https://studio.docs.ai.vonage.com/voice/nodes/basic/q-and-a-node#search).
{% endhint %}
Use **Response guidelines** to set the tone, format, and scope of Knowledge AI responses with custom instructions.
* Tone: formal, friendly, concise, and similar options.
* Topic restrictions: prevent the assistant from responding to out-of-scope queries.
* Custom guardrails: rules for responses based on testing feedback.
* Company-specific terminology: ensure branding consistency. For example, use "Vonage" instead of "we".
These guidelines help align your assistant's voice with your brand and use case.
Best practices for Response guidelines
Use **Response guidelines** to define how Knowledge AI should respond, covering tone, structure, and topic scope. This helps ensure responses are clear, accurate, and aligned with your brand.
**1. Keep it simple**
Start with 3 to 4 key rules. Too many constraints can reduce model performance.
Do not repeat system logic:
* Do not define the "Don't Know" response. The logic for vague or missing answers is predefined in the backend. Avoid instructions such as: "If the input is vague, say 'I'm not sure'" or "Only provide a found response."
* Do not define the role. The Q\&A node's role is also predefined. Avoid instructions such as: "You are a virtual agent for XYZ handling ABC topic."
**2. What to include**
When writing custom instructions, focus on the following areas:
| Category | What to define | Example |
| ------------ | --------------------------------- | ------------------------------------------------------------------------- |
| Tone | The tone and style for responses. | Formal, friendly, empathetic, or instructional. |
| Topic scope | What is in or out of scope. | "Answer only questions about product and billing." |
| Terminology | Brand or company language. | Use "Vonage" instead of "we." |
| Custom rules | Guidance based on testing. | Adjust clarity, phrasing, or coverage. Do not include long lists of URLs. |
**3. Write clear instructions**
Provide examples of correct and incorrect responses so Knowledge AI can interpret your intent accurately.
{% code overflow="wrap" %}
```
Instruction: Summarize retrieved information in a clear, neutral, and concise tone.
Correct behavior: Studies show that moderate protein intake and reduced refined carbohydrates can lower diabetes risk.
Incorrect behavior: Wow, carbs are terrible! Everyone should stop eating rice immediately. (Subjective, emotional, and exaggerated tone.)
```
{% endcode %}
**4. Test and refine**
Review outputs and adjust your guidelines based on user testing or QA feedback.
{% hint style="warning" %}
**Single-turn processing**
Knowledge AI operates in single-turn mode:
* The Q\&A node processes one input and returns one output.
* After returning the response, the node is marked as completed.
* It does not support back-and-forth conversation. To reuse the same Q\&A node, add a loop in your VA flow.
* For setup instructions, see [Using the Q\&A node in your VA flow](https://studio.docs.ai.vonage.com/voice/nodes/basic/q-and-a-node#using-the-q-and-a-node-in-your-va).
{% endhint %}
### Waiting time
**Waiting time** determines how long the VA waits for a response from Knowledge AI.
* Default: 3 seconds
* Configurable range: 2 to 10 seconds
{% hint style="success" %}
**Choosing the right waiting time**
* Shorter wait times feel more natural in human conversation.
* Longer wait times reduce API timeout risk but may affect flow pacing, especially for voice channels.
{% endhint %}
***
## Managing Outputs
The **Output mode** setting defines how Knowledge AI processes and returns information from your Knowledge Base.
There are two modes available:
* **Search & Respond**.
* **Search**.
| Category | Search & Respond | Search |
| -------------------------------------------- | ------------------------------------------------------------ | -------------------------------------------------------- |
| What it returns | A single, refined text answer ready to send to the end user. | Raw text chunks retrieved from the knowledge base. |
| Typical output size | 100 to 500 characters. | 250 to 2500 characters per chunk. |
| Best for | Customer-facing conversational flows. | Passing retrieved content to another AI process or agent |
| Answer length and Response guidelines fields | Available | Disabled |
### **Search & Respond**
**Search & Respond** is the default output mode. Knowledge AI searches your knowledge base, passes the retrieved content to an LLM, and returns a single concise answer directly to the end user. Use this mode when you want Knowledge AI to handle both retrieval and response generation automatically.
Output characteristics:
* Responses are typically 100 to 500 characters long.
* Answers are short, structured, and optimized for clarity.
* Best suited for customer-facing conversational use cases.
### **Search**
**Search** mode retrieves the most relevant text chunks from your knowledge base without generating a summarized response. The raw content is returned for further processing by another AI process, workflow, or agent. Use this mode when Knowledge AI acts as a tool within an AI Agent, or when minimising latency is a priority.
Output characteristics:
* The output consists of multiple text chunks, typically ranging from 250 to 2500 characters each.
* The raw text may include long passages or multiple paragraphs.
* It is not recommended to send this output directly to end users.
{% hint style="warning" %}
**Disabled fields in Search mode**
When **Output mode** is set to **Search**, the **Answer length** and **Response guidelines** fields are disabled in both the Q\&A node and the Index Tester.
{% endhint %}
***
## Diagnosing Knowledge AI outputs
If Knowledge AI returns incomplete or incorrect answers, check its behavior manually using AI Studio Reports or the upcoming Knowledge AI Insights.
The following table describes common issues and recommended actions:
| Problem | Likely Cause | Recommended Action |
| ---------------------------- | ---------------------------------------------- | ------------------------------------------------------- |
| Ambiguous user question | Query is unclear or incomplete. | Ask the user to clarify or rephrase within the VA flow. |
| Outside Knowledge Base scope | The Index lacks relevant data. | Add new, relevant material to the Knowledge Base. |
| Search issue | Information exists but is not being retrieved. | Review and optimize source formatting. |
| Partial or inaccurate answer | Model retrieved but misunderstood content. | Improve Source structure or revise Response Guidelines. |
***
## Using the Q\&A Node in your VA
The Q\&A node is most effective when used as part of a broader conversational setup. The following are common patterns:
* Collect Input node, then Q\&A node, then return result.
* Use as a fallback if other nodes fail.
* Route back to the Q\&A node after collecting more context.
{% hint style="warning" %}
**Context not retained between uses**
The Q\&A node does not retain previous answers. Add context before sending the query if needed.
You can also use the [Context Switch node](https://studio.docs.ai.vonage.com/voice/nodes/flow-control/context-switch) to allow the VA to pivot between topics.
{% endhint %}
***
## Related Links
* [Knowledge AI Overview](https://studio.docs.ai.vonage.com/ai-studio/knowledge-ai#smarter-brand-safe-answers-with-generative-ai)
* [Index Tester](https://studio.docs.ai.vonage.com/ai-studio/knowledge-ai#create-indexes-group-your-sources)
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://studio.docs.ai.vonage.com/voice/nodes/basic/q-and-a-node.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.